Proxies for AI Training Data Collection
Proxies for AI training data let your crawler collect fresh public pages through residential IPs in 195+ countries, with fewer IP-related blocks. ColdProxy's Residential IPv4 (Unmetered) gives unlimited traffic at the speed tier you choose, so every refresh and re-crawl stays off a per-GB meter.

Unlimited traffic on speed-tier plans
Country, State, and City targeting
Pilot by the hour on Residential IPv4 (Unmetered)
What to know first
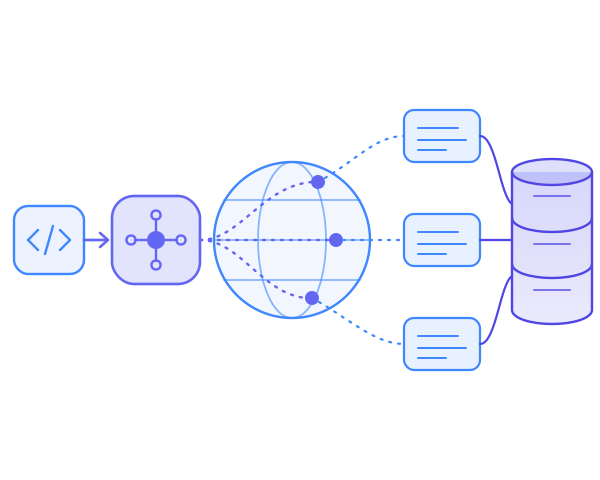
A proxy sends your crawler's requests out through other IP addresses, spreading a training-data crawl across many IPs and the countries you choose. Start with Common Crawl or open datasets for broad text, then crawl the fresh, targeted or regional pages they miss. For large or repeated crawls, ColdProxy's Residential IPv4 (Unmetered) gives unlimited traffic at your speed tier. If your sources are on IPv6 or a supported CDN, Datacenter IPv6 covers 45+ locations in one order.
What Are The Challenges in AI Training Data Collection?
AI training data collection meets four problems that grow with the crawl: stricter limits on cloud IPs, per-GB bills on every re-crawl, one country's version of the web, and sessions that break mid-source. Open datasets get you started; these problems hit the crawl that fills their gaps.

Cloud IPs Hit Stricter Limits
Many sites apply stricter limits and IP-related blocks to cloud server ranges, so a crawler running from a few servers can meet 429 errors even at a polite per-domain rate.

Per-GB Bills Grow With Every Re-Crawl
Training data goes stale. Each refresh, retry and browser render downloads pages again, and on per-GB billing the cost climbs with every pass.

One Country's Version of the Web
Sites change language, prices and content by visitor location. Crawl everything from one region and that region's view dominates your training set.

Sessions That Break Mid-Source
Paginated listings expect the same visitor from page to page. An IP that changes mid-sequence can cut a source off before the last page.
Do You Need Proxies, or Is Common Crawl Enough?
Often you need both. Start with Common Crawl and open datasets such as FineWeb or C4 for broad text: free, already huge and ready to filter. Add proxies for what they miss: fresh versions of pages, specific countries or languages, and full coverage of the domains you need.
Open datasets give you
Broad, general text for pre-training, historical snapshots, and a baseline to deduplicate against before you crawl anything yourself.
Your own crawl adds
Pages that changed since the last snapshot, sources in a specific country or language, domains you need in full, and the reach a polite crawl loses when sites limit or block your cloud servers' IP ranges.
How ColdProxy Works for AI Training Data
ColdProxy fits a training-data crawl in four steps: list what open datasets miss, pick the plan by source, set location and session, then pilot on an hourly or daily plan and scale.
List the Gap
Start from open datasets, then list the sources, countries and languages they miss. That list sets the size of your crawl.
Pick the Plan by Source
Residential IPv4 for most public sites. An IPv6 plan when a source is on IPv6 or a supported CDN; the IPv6 Checker shows its IPv6 addresses and a short pilot tests the fit.
Set Location and Session
Add a country, state or city and a rotating or sticky session to the proxy username. With IP Auth, set them once for a port range with SuperPorts port-range settings instead.
Pilot, Then Scale
Run a sample of each source on an hourly or daily Residential IPv4 (Unmetered) plan, measure pages, bytes and errors, then choose the speed tier for the full crawl. The proxy trial checklist covers what else to test.
Which Proxy Fits Your Training-Data Sources?
For most public-web training crawls, start with Residential IPv4 (Unmetered). Then match the plan to how your sources behave and how often you re-crawl them.
Up to about 1.08 TB a dayat full speed on the 100 Mbps Residential IPv4 (Unmetered) tier
On speed-tier plans, pay for speed, not gigabytes. The 100 Mbps Residential IPv4 (Unmetered) tier costs $58.89 a day or $1,317.49 a month, however much your crawler downloads. At full speed, each 1 Mbps can move about 10.8 GB a day, on tiers from 5 Mbps to 1000 Mbps. Real throughput depends on your sources and crawler.
- Start here for large or repeated crawlsResidential IPv4 (Unmetered) pricingUnlimited traffic at your Mbps tier, from hourly to monthly, with automatic setup (up to 10 minutes).
- A smaller crawl you can size in advanceResidential IPv4 (GB Based) pricingMonthly traffic packs with instant activation.
- US sources on IPv6 or a supported CDN that need residential IPsResidential IPv6 pricingUSA residential IPv6 with unlimited traffic at your tier and instant activation.
- Sources on IPv6 or a supported CDN, in many countriesDatacenter IPv6 pricingA private /48 in each of 45+ supported locations, all in one order, with automatic setup (up to 10 minutes).
Not sure a source publishes IPv6 addresses? Check it with the free IPv6 Checker before you pick an IPv6 plan.
| Feature | Residential IPv4 | Datacenter IPv6 |
|---|---|---|
| Best For Training Data | Most public sites, regional and multilingual sources | Sources on IPv6 or a supported CDN, fast repeated crawls; some sites apply stricter limits to cloud ranges |
| Geo-Targeting | Country targeting in 195+ countries; city where local supply exists; state or region in six countries | Country and city in 45+ locations across 25 countries |
| Session Control | Rotating + sticky (5 seconds to 24 hours) | Rotating + sticky (5 seconds to FOREVER) |
| Speed | Up to 0.6s response time | Mbps speed tiers |
| Buying Model | Mbps speed tiers with unlimited traffic, or monthly GB packs | Mbps speed tiers with unlimited traffic |
Prices for Training-Data Crawls
Prices for the four plans above, in order; each Mbps can move about 10.8 GB a day at full speed.

Premium Residential
Geo Target IPv4
(Unmetered)
- Country, state, and city targeting
- Rotating or sticky sessions (5 seconds to 24 hours)
- Mbps speed tiers
- HTTP, HTTPS, and SOCKS5
- User:Pass or IP Auth
- 1 to 5,000 unique ports
- 24/7 support
From $2.49/hour
Current price: $4.74/day
5 Mbps speed tier · unlimited traffic

Premium Residential
Geo Target IPv4
(GB Based)
- Country, state, and city targeting
- Rotating or sticky sessions (5 seconds to 24 hours)
- Monthly traffic packs
- HTTP, HTTPS, and SOCKS5
- User:Pass or IP Auth
- 1 to 5,000 unique ports
- 24/7 support
From $1.27/month
Current price: $1.27/month
1 GB traffic pack

Residential IPv6
- USA-only Residential IPv6 (Ashburn, USA)
- Included /32 IPv6 subnet
- Sticky sessions from 5 seconds to FOREVER or rotating
- Mbps speed tiers
- HTTP, HTTPS, and SOCKS5
- User:Pass or IP Auth
- 1 to 5,000 unique ports
From $0.99/hour
Current price: $3.99/day
10 Mbps speed tier · unlimited traffic

Datacenter IPv6
- All supported Datacenter IPv6 locations
- Private /48 per supported location
- Sticky sessions from 5 seconds to FOREVER or rotating
- Mbps speed tiers
- HTTP, HTTPS, and SOCKS5
- User:Pass or IP Auth
- 1 to 5,000 unique ports
From $3.80/day
Current price: $3.80/day
15 Mbps speed tier · unlimited traffic
How Web Scraping Feeds AI Training Data
Web scraping feeds AI training data by collecting the public pages a model learns from. These five source types come up most, with the plan or setting that usually fits.
Documentation & Technical Q&A
Product docs, changelogs and public developer Q&A give code-aware models current, well-structured text. Docs change with every release, so re-crawls add up; a speed-tier plan keeps them off a per-GB meter.
Product Catalogs & Public Reviews
Listings, specs and public reviews show how products are described and compared in each market. Country targeting fetches each catalog from an IP inside that market, the version sites serve to local visitors.
News & Public Research
News sites, preprints and public reports keep a dataset current. Rotate per request across many publishers and refresh each one as often as it publishes.
Regional & Multilingual Sites
Low-resource languages and regional editions are where open datasets are thinnest. Residential IPv4 reaches 195+ countries, with state or region targeting in six of them and city where local ISP supply exists. Check the Residential IPv4 pool data by country before you set quotas.
Public Listings & Directories
Business directories and public listings give structured records for extraction models. A sticky session holds a working IP for the window you set, so paginated results can come from one address.
For crawls outside AI training, see web scraping proxies. For where a proxy sits in the rest of an ML pipeline, read how proxies fit a machine-learning data workflow.
Quick Start: Connect Your Training-Data Crawler
ColdProxy works with Python, Scrapy, Node.js and any crawler that accepts standard proxy settings. Each example names its bot; the Python and Scrapy examples also check robots.txt before fetching.
import requests
from urllib.robotparser import RobotFileParser

# Rotating US residential IP on every request
PROXY = "http://USER-country-us:PASS@gw-2312.coldproxy.com:30000"
proxies = {"http": PROXY, "https": PROXY}
BOT = "ExampleDatasetBot/1.0 (+https://example.com/bot)"

# Read robots.txt through the proxy before fetching pages
robots = RobotFileParser()
robots_txt = requests.get("https://example.com/robots.txt", proxies=proxies,
                          headers={"User-Agent": BOT}, timeout=30)
if robots_txt.status_code in (401, 403, 429) or robots_txt.status_code >= 500:
    robots.disallow_all = True   # denied or unavailable: fetch nothing
elif robots_txt.ok:
    robots.parse(robots_txt.text.splitlines())
else:
    robots.allow_all = True      # no robots.txt (for example 404): no rules

url = "https://example.com/docs/getting-started"
if robots.can_fetch(BOT, url):
    page = requests.get(url, proxies=proxies, headers={"User-Agent": BOT}, timeout=30)
    print(page.status_code, len(page.content))
Replace USER and PASS with your proxy username and password, and gw-2312.coldproxy.com:30000 with the gateway host and port shown in your client area. See how to connect to your proxy.
Collect Training Data Responsibly
A proxy changes the IP your requests come from. It does not change a site's terms or the rules that apply to you. We recommend these practices for every training-data crawl.
Follow Site Terms and robots.txt, Including AI-Crawler Rules
Our Terms of Service don't allow data scraping against a site's terms of use, so check each source's terms before you add it. We also recommend honouring robots.txt: many sites now set separate rules for AI crawlers, so check every user agent your crawler matches.
Identify Your Crawler
Send a user agent that names your bot and links to a page with contact details, so site owners can reach you.
Keep Per-Domain Rate Limits
Spread requests across many domains and keep each site's request rate low. More IPs are no reason to hit one site harder.
Leave Out Logins, Paywalls and Personal Data
Collect public pages only, and filter personal data out of the corpus.
Record Where Every Document Came From
Store the URL, fetch time, exit country and status with each document. Provenance makes dedup, audits and removal requests manageable.
Re-Crawl by Change Rate
Refresh news and listings often and documentation on release, instead of re-crawling everything on one schedule.
Under our Acceptable Use Policy, you are responsible for how you use the service and for keeping that use within the law, and you may not infringe others' rights, including intellectual property and privacy rights; our Terms of Service set out your obligations as a user. Get your own legal review for your sources and jurisdiction, and see our ethical web scraping guide.


Check each new source for IPv6 as your crawl grows
An IPv6 plan fits a source that publishes IPv6 addresses or sits on a supported CDN. See whether each new site publishes IPv6 addresses before you route it through Datacenter IPv6 or Residential IPv6. Free, no signup.
Questions About Proxies for AI Training Data
Plan choice, billing, targeting and responsible collection for training-data crawls.
Yes, when your sources are on IPv6 or a supported CDN: ColdProxy's datacenter proxies are Datacenter IPv6, which suits AI training data collection from those sources. One order includes all 45+ supported locations, United States cities among them, with a private /48 per location and unlimited traffic at your Mbps tier for fast, repeated crawls. Some sites apply stricter limits to cloud ranges. Check each source with the free IPv6 Checker first, and use Residential IPv4 for other sources. A proxy doesn't change what you're allowed to collect: each site's terms and the rules that apply to you stay the same.
The best proxies for AI training data collection depend on your sources and how often you re-crawl them. For most public-web training crawls, ColdProxy's Residential IPv4 (Unmetered) fits best, with residential IPs in 195+ countries and unlimited traffic at your speed tier. Use Residential IPv4 (GB Based) for a smaller crawl you can size in advance, and Datacenter IPv6 or Residential IPv6 (USA-only) when your sources are on IPv6 or a supported CDN.
Four things matter most for large-scale AI training data collection: a buying model that doesn't charge for every re-crawl, the countries you can reach, session control and what the provider logs. ColdProxy's Residential IPv4 (Unmetered) gives unlimited traffic at your Mbps tier and residential IPs in 195+ countries, with rotating or sticky sessions from 5 seconds to 24 hours, and ColdProxy doesn't log which sites your crawler visits. Run a short hourly pilot before you scale.
Start with Common Crawl and open datasets for broad text. Add proxies when you need what they miss: fresh versions of pages, specific countries or languages, or full coverage of chosen domains. Proxies also help when sites apply stricter limits or IP-related blocks to your cloud servers' IP ranges, even at a polite per-domain rate.
Traffic for a training-data crawl depends on page size, browser renders and how often you re-crawl. ColdProxy bills Residential IPv4 (Unmetered), Residential IPv6 and Datacenter IPv6 by Mbps speed tier, with unlimited traffic during the period, so re-crawls and retries carry no per-GB charge. Residential IPv4 (GB Based) is billed in monthly traffic packs.
Yes, you can target countries and regions to balance a training dataset. Residential IPv4 supports Country, State, and City targeting in 195+ countries: state or region in the United States, United Kingdom, Germany, Brazil, India and Canada, and city where local ISP supply exists. Set a quota per country or language and route each share through matching IPs.
ColdProxy doesn't sell ISP proxies; for AI training data collection that needs residential IPs, including from the United States, it offers Residential IPv4 instead. Residential IPv4 has residential IPs in 195+ countries, with rotating sessions or sticky sessions from 5 seconds to 24 hours; a sticky session holds a working IP for the window you set, so you can page through a source on one address.
The term "AI proxy" has two meanings. An LLM API proxy or gateway sits between your app and a model provider. A proxy for AI data collection, which is what ColdProxy sells, routes your crawler's requests through other IP addresses so it can collect public web data from many locations.
The ColdProxy residential proxy pool is ethically sourced and held to strict compliance standards.
No, a proxy doesn't change what you're allowed to collect. It changes only the IP address your requests come from; a site's terms and the rules that apply to you stay the same. Our Terms of Service don't allow data scraping against a site's terms of use, and our Acceptable Use Policy sets out the other rules for using the service. We recommend honouring robots.txt and getting your own legal review for your sources and jurisdiction.
To test ColdProxy before you scale, check your sources with the free IPv6 Checker and your setup with the free Proxy Checker. Then run a short paid pilot: hourly on Residential IPv4 (Unmetered) or Residential IPv6 where available, daily on Datacenter IPv6, or a monthly pack on Residential IPv4 (GB Based). Free trials may be available after individual review. Tell us what you want to test and the capacity you need. We assess each request and confirm availability and trial terms before providing access.
No. ColdProxy doesn't keep logs of the websites your crawler visits through the proxy service, the content of its traffic, or which of our IP addresses each connection used. Account, billing, usage totals and security records are kept as our Privacy Policy describes.
Still have questions? See the full FAQ or contact our team.

Need a tailored proxy plan for a large project?
Need a different speed or traffic allowance? Contact us through the channels on our website so we can assess whether a custom plan is possible.